News · Tech
DeepX tapes out DX-M2, a 2nm chip designed to run 100B-parameter models in about 5 watts
South Korean startup DeepX has taped out its second-generation DX-M2 accelerator on Samsung's 2nm process. It is designed to run 20B to 100B parameter language models on robots, drones and PCs at 10 to 30 tokens per second within a 5 watt chip budget, with first silicon due in March 2027.
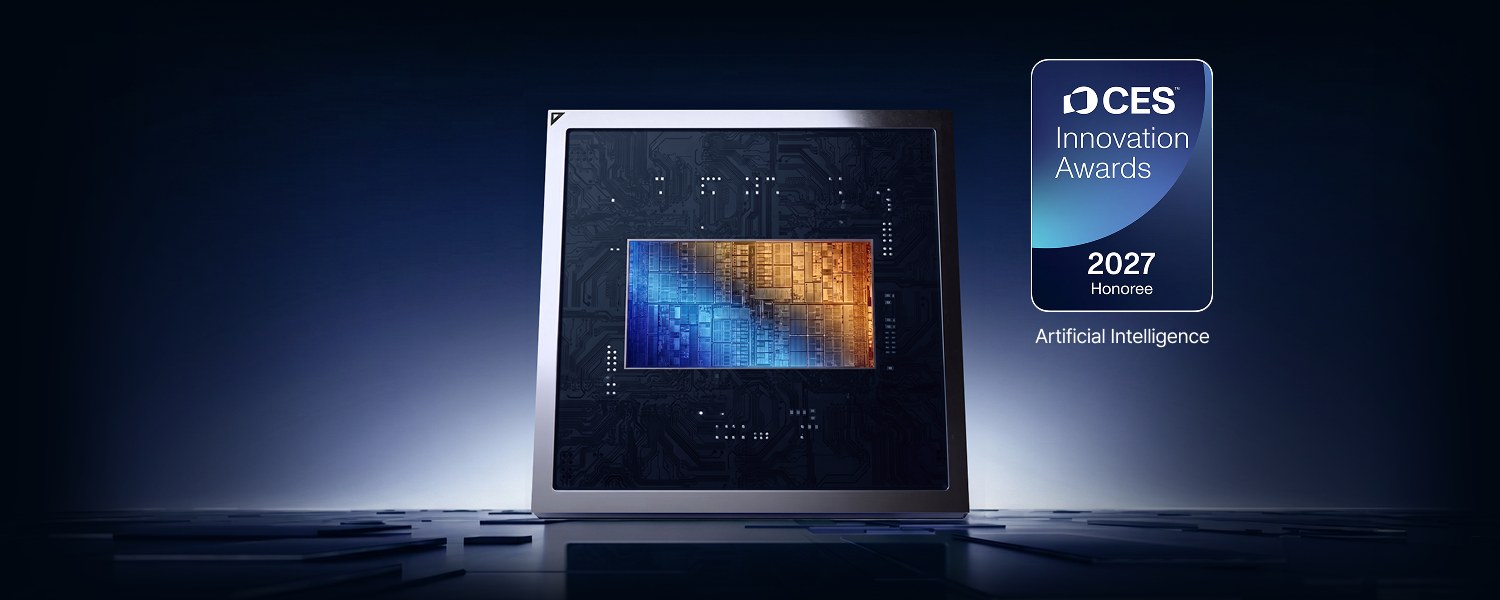
South Korean edge AI chip startup DeepX has taped out the DX-M2, its second-generation accelerator, on Samsung Foundry's 2nm process[1][2]. Tape-out means the design is finished and handed to the foundry for manufacturing. The chip is pitched at running large language models on robots, drones and other battery-powered devices, with up to 100 billion parameters inside a 5 watt chip budget[1].
01 / 05
The numbers
DeepX says the DX-M2 runs models of 20 billion to 100 billion parameters, roughly 3 billion to 20 billion active, at 10 to 30 tokens per second depending on the model[1]. Memory bandwidth triples from 50 GB/s on the first-generation DX-M1 to about 150 GB/s, and the NPU reaches 80 TOPS. DeepX credits design changes with doubling power efficiency and the move to 2nm with doubling it again[1].
The 5 watt figure covers the chip, not the whole system. DeepX's own product page lists 5W for the SoC only on the standard package with up to 96GB of external LPDDR5X, and 8.5W for a Pro module with memory included[3]. The chip also supports large mixture-of-experts models, speculative decoding and TurboQuant[1].
02 / 05
Memory that does maths
DeepX has spent a year and a half working with Samsung to pair the DX-M2 with Samsung's LPDDR5X-PIM, memory that can run memory-bound operations itself instead of shipping weights back and forth[1]. In DeepX's simulations, offloading those operations gives 6.7 times the tokens per second on Llama 3.1 8B, though it needs 2.7 times the power. The company thinks it can get about twice the performance within the normal power budget, and says its PIM compiler is still a prototype running against a simulation[1].
03 / 05
Who it is for
DeepX is targeting robotics companies that prototype on Nvidia GPUs and then hit power and heat limits, as well as AI PCs, in-car agents and smart home hubs[1]. It has built robotics libraries called DX-Newton meant to mirror Nvidia's Isaac APIs, so developers can switch by changing the API name, though a full robotics stack is still in development. Hyundai Motor Group's Robotics Lab already uses the DX-M1[1].
The first-generation DX-M1 is in mass production. DeepX told EE Times it has more than 100 purchase orders[1], while The Korea Times reported 88 commercial orders worth about US$13.3 million as of October[2]. The DX-M2 has also been named a CES 2027 Innovation Awards honoree in the AI category[2].
04 / 05
When it ships
DeepX expects first silicon in March 2027, customer sampling in the second quarter and initial production volumes in the fourth quarter of 2027, with full-scale mass production in 2028[2]. A chiplet-based DX-M3 using LPDDR6-PIM is on the roadmap for 2028, aimed at carmakers and humanoid robot builders[1].
05 / 05
Why it matters
Most on-device AI chips today handle vision tasks like object detection. If the DX-M2 hits its targets in real silicon, a drone or robot could run a model in the 100 billion parameter class locally, without a network link or a power-hungry GPU. The big caveats are that today's figures are design targets and simulations, and that system power will be higher than the headline 5 watts once memory is counted.
FAQ
Frequently asked questions.
01What is the DX-M2?
DeepX's second-generation AI accelerator, built on Samsung Foundry's 2nm process. It is designed to run generative AI, including large language and vision-language models, directly on robots, drones, PCs and other edge devices instead of in the cloud.
02How big a model can it run?
DeepX says models of 20 billion to 100 billion parameters, roughly 3 billion to 20 billion active parameters for mixture-of-experts models, at 10 to 30 tokens per second depending on the model.
03Is it really 5 watts?
The 5 watt figure is for the chip itself. DeepX's product page lists 5W for the SoC only on the standard package, with external memory on top, and 8.5W for a Pro module that includes memory.
04What does Samsung's PIM memory add?
Processing-in-memory lets the memory chip do some maths itself. DeepX's simulations show 6.7 times the tokens per second on Llama 3.1 8B when pairing DX-M2 with Samsung LPDDR5X-PIM, but at 2.7 times the power. Those figures are simulated, not measured on silicon.
05When can companies get it?
DeepX expects first silicon in March 2027 and customer sampling in the second quarter, with initial production volumes in late 2027 and full-scale mass production in 2028.
That’s the story
Building with what’s new?
Spectrum Web Co ships products, places talent, builds social narratives and builds custom business tools as monthly services.
Related stories